Biopharmaceutical manufacturing increasingly uses mechanistic models, statistical predictors, process analytical technologies, metabolic reconstructions, and digital-twin concepts to anticipate culture behavior and product quality. However, an accurate predictor of a selected process variable is not necessarily a model of the evolving manufacturing system. It may lack a persistent representation of cell state, explicit intervention semantics, multiscale temporal dynamics, calibrated uncertainty, or a traceable connection between process actions and critical quality attributes. This article proposes a bioprocess world-model architecture as an original conceptual synthesis for representing partially observed manufacturing systems and simulating conditional future consequences. The architecture separates measurements from latent biological and process states, represents interventions as explicit inputs to temporal transitions, couples intracellular, cellular, population, extracellular, equipment, and product-quality layers, and propagates multiple forms of uncertainty. Sensor and analytical data are incorporated through controlled state estimation, recalibration, and structurally governed updating rather than unrestricted continual learning. Validation is framed as perturbation-based consequence prediction: alternative interventions should be simulated from comparable initial states and assessed against prospective or held-out biological, process, and quality outcomes. Proposed readiness levels distinguish conceptual specification, verified components, retrospective coherence, prospective prediction, perturbation validity, and bounded decision evaluation. Major failure modes include partial observability, non-identifiability, policy confounding, clonal and analytical drift, omitted-state error, scale dependence, and unsupported extrapolation. The architecture does not establish empirical validity, manufacturing benefit, regulatory acceptance, or universal applicability. Its contribution is a testable framework for organizing models, observations, interventions, uncertainty, quality consequences, and evidence requirements within explicitly declared manufacturing boundaries.
INTRODUCTION
Biopharmaceutical process models increasingly function as computational replicas of selected manufacturing operations. Such replicas can consolidate mechanistic knowledge, process data, and simulated trajectories, but their represented boundaries, update mechanisms, and intended uses vary substantially [1].
Digital-twin research in mammalian cell culture has extended this ambition toward connected systems for monitoring, prediction, process understanding, and control. Nevertheless, most implementations remain organized around defined products, unit operations, measurements, and modeling tasks rather than a complete representation of the changing manufacturing system [2].
Bioprocessing 4.0 further situates models within interconnected sensing, data-management, automation, and decision infrastructures. This broader environment makes integration important, but technological connectivity alone does not establish that a model can preserve biologically meaningful state, simulate alternative interventions, or predict downstream quality consequences [3].
This Original World-Model Architecture Article proposes a bioprocess world model as a bounded, partially observed, action-conditioned representation of manufacturing evolution. The contribution integrates cell-state dynamics, population change, process interventions, uncertainty, analytical updating, and critical-quality-attribute prediction while distinguishing conceptual plausibility from empirical validation and decision readiness.
Why predictive process models are not complete world models
Predictive process development commonly decomposes manufacturing into tractable tasks, such as estimating metabolite concentrations, forecasting viable-cell density, detecting deviations, or optimizing operating conditions. Although valuable, this decomposition can leave models disconnected from the lifecycle, data, and decisions through which their predictions acquire meaning [4].
Hybrid modeling addresses part of this limitation by combining mechanistic structure with data-driven flexibility. Such models may improve interpretability or predictive coverage, but hybridization does not itself provide persistent state estimation, explicit intervention semantics, counterfactual trajectories, or a quality-consequence representation [5].
Model architecture also matters. Different coupling strategies, mechanistic assumptions, training procedures, and model interfaces can produce materially different representations of the same bioprocess. These structural choices create practical risks involving identifiability, data sufficiency, extrapolation, maintenance, and interpretation [6].
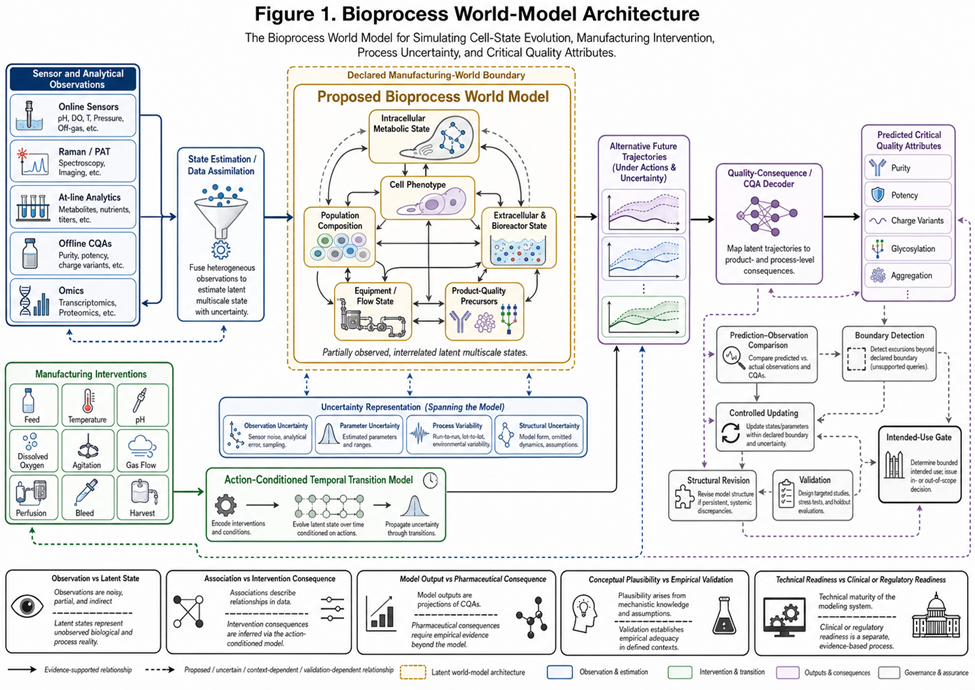
A complete world model is therefore not defined by model size or predictive accuracy alone. It requires a declared world boundary, a temporally updated internal state, explicit manufacturing actions, multiscale transition mechanisms, uncertainty representation, and traceable propagation from intervention to biological, process, and product-quality consequences.
Figure 1 presents the original conceptual synthesis for bioprocess world-model architecture, showing how the article’s principal components, evidence relationships, uncertainties, and decision boundaries are connected.
|
|
|
Figure 1. Bioprocess World-Model Architecture |
Definitions and requirements of a bioprocess world model
In computational control, a world model can be understood as an internal representation that supports action-conditioned imagined trajectories. Transferred cautiously to biomanufacturing, this principle means that a model should represent how a process may evolve under specified actions rather than merely extrapolate an observed signal [7].
The world is the explicitly bounded manufacturing system whose decision-relevant states and transitions are represented. Genome-scale CHO models can contribute an intracellular metabolic layer, but they do not independently represent population distributions, equipment behavior, analytical observation processes, interventions, or complete product-quality consequences [8].
A bioprocess world model is proposed here as a partially observed dynamical architecture that maintains a belief about current multiscale state, updates that belief from measurements, and simulates conditional future states and quality consequences. Emerging predictive CHO digital twins illustrate elements of this integration while remaining cell-line-, process-, data-, and product-dependent [9].
Minimum requirements are a declared world boundary, latent-state representation, observation model, intervention model, temporal-transition mechanism, quality-consequence model, uncertainty representation, update rules, and intended-use definition. A model lacking one component may remain useful, but its claims should be restricted to the capabilities it actually possesses.
The term does not imply a complete molecular replica of a cell factory or a universally faithful simulation of manufacturing reality. Relevant state variables may remain unobserved or non-identifiable, and different products, cell-free systems, synthetic-biology platforms, scales, and unit operations may require different world boundaries and architectures.
State, intervention, time, and uncertainty representation
State should describe the information required to predict decision-relevant future evolution. Dynamic constraint-based CHO models show that growth, extracellular composition, intracellular fluxes, and clonal behavior change jointly over process time, supporting a representation that extends beyond isolated measurements [10].
An observation is not identical to the underlying state. Sensor values, Raman spectra, metabolite assays, viable-cell measurements, omics profiles, and quality analytics provide incomplete and noisy views of biological and process conditions. Structural uncertainty in biochemical networks must also be distinguished from ordinary measurement error, especially when available data cannot discriminate among alternative mechanisms [11].
Interventions should be encoded separately from disturbances and passive covariates. Feed changes, temperature shifts, gas-flow adjustments, perfusion actions, and harvest decisions are deliberate manipulations, whereas raw-material variability, sensor drift, and unmeasured biological changes may alter trajectories without representing chosen actions. Omics-informed hybrid dynamics demonstrate how mechanistic and data-driven representations can be combined while propagating uncertainty [12].
The proposed architecture consequently represents a distribution over plausible states rather than a single certain trajectory. It distinguishes observation, parameter, process, and structural uncertainty; preserves irregular measurement timing; and conditions future-state distributions on explicit interventions. These distinctions are requirements for testable counterfactual simulation, not evidence that complete uncertainty decomposition is currently achievable.
Proposed multiscale model architecture
The proposed architecture contains interoperable models rather than one monolithic predictor. Its intracellular layer constrains feasible metabolic states using enzyme-capacity information, thereby linking resource allocation to culture behavior [13].
A quality-linking layer translates selected metabolic and process states into product-quality precursors. Hybrid stoichiometric and neural modeling shows that such mappings can connect CHO-cell metabolism with antibody glycosylation patterns [14].
A culture-scale layer represents extracellular conditions, biomass, viable-cell dynamics, exchange fluxes, and process operations. Enzyme-constrained dynamic flux analysis demonstrates how intracellular and culture-scale representations may be coupled while retaining uncertainty [15].
Together, enzyme-capacity constraints, quality-linked hybrid mappings, and uncertainty-aware multiscale coupling justify the three-model core of the proposed architecture [13-15].
The complete architecture additionally requires observation models, intervention interfaces, population-state representations, equipment context, controlled updating, boundary detection, and intended-use governance. These interfaces are proposed and require product-, scale-, and process-specific validation.
Cell-state and population evolution
Cell state should describe more than average viable-cell density. Industrial fed-batch studies show that contextualized CHO metabolic models can represent changing intracellular activity under process-specific conditions [16].
Population averages may conceal distinct phenotypes or metabolic phases. Multiscale culture models indicate that heterogeneous transitions can alter aggregate process behavior and should therefore be represented explicitly where relevant [17].
Single-cell trajectory methods provide a transferable principle for reconstructing latent dynamic paths from partial observations [18]. Their application to manufacturing would nevertheless require appropriate measurements, lineage assumptions, and validation in production-relevant cell systems.
The proposed population state consequently includes phenotype distributions, metabolic phases, growth and death tendencies, and uncertainty about unobserved subpopulations. It does not claim direct observation of every cell or lineage.
Table 1 organizes the evidence, constructs, relationships, uncertainties, and boundary conditions required for definitions, components, relationships, and intended uses in the bioprocess world model for simulating cell-state evolution, manufacturing.
Table 1. Definitions, components, relationships, and intended uses in The Bioprocess World Model for Simulating Cell-State Evolution, Manufacturing.
|
Component or scientific dimension |
Problem addressed |
Inputs or determinants |
Proposed mechanism or relationship |
Expected contribution |
Evidence required |
Failure or uncertainty risk |
Boundary statement |
|
Declared manufacturing world |
Prevents undefined model scope |
Product, cell line, unit operation, scale, operating range |
Defines which states, actions, and consequences belong to the modeled system |
Interpretable intended use |
Documented process and decision context |
Hidden exclusions or unsupported extrapolation |
Proposed construct; not universal |
|
Intracellular state |
Represents metabolic constraints |
Nutrients, enzyme capacity, exchange fluxes |
Constrains feasible intracellular transitions [13] |
Mechanistic consistency |
Flux, metabolite, and perturbation evidence |
Non-identifiability and incomplete networks |
Does not represent the whole cell |
|
Cell and population state |
Captures heterogeneity |
Phenotypes, phase transitions, viability, single-cell signals |
Population composition evolves through partially observed transitions [17] |
Explains aggregate changes |
Population-resolved and temporal data |
Averaging, sampling bias, uncertain lineages |
Trajectories remain model-dependent |
|
Process state |
Connects cells with their environment |
Medium, gases, temperature, mixing, equipment context |
Extracellular and engineering conditions alter cellular transitions |
Cross-scale consequence prediction |
Scale-appropriate process measurements |
Scale dependence and omitted engineering variables |
Validity is process-specific |
|
Intervention model |
Separates actions from correlation |
Feed, temperature, gas, perfusion, bleed, harvest |
Actions condition future-state distributions |
Alternative-action simulation |
Controlled intervention contrasts |
Confounding and unsupported action ranges |
Association alone is insufficient |
|
Quality-consequence layer |
Links evolution to product quality |
Metabolic, process, and analytical states |
Intermediate states generate distributions over selected CQAs [14] |
Traceable quality prediction |
Direct CQA measurements and mediator evidence |
Surrogate failure and product specificity |
Prediction is not release authorization |
|
Observation and update layer |
Handles partial observability |
Sensors, Raman, omics, at-line and offline assays |
Measurements update uncertain latent states |
Current-state estimation |
Calibrated analytical data |
Sensor drift, missingness, measurement bias |
Observations are not identical to state |
|
Uncertainty representation |
Prevents false precision |
Noise, parameters, structural alternatives, unfamiliar states |
Propagates uncertainty through transitions and CQAs [15] |
Calibrated confidence and boundary alerts |
Prospective calibration evidence |
Underestimated structural uncertainty |
Complete decomposition may be impossible |
|
Readiness and intended-use gate |
Restricts premature decision use |
Validation status, risk, operating boundary |
Permits, limits, or rejects specific uses |
Evidence-bounded application |
Intended-use-specific validation |
Readiness inflation |
Proposed, non-regulatory classification |
Process intervention and counterfactual simulation
Multistep forecasting estimates how an observed process may continue, and its reliability can deteriorate with prediction horizon [19]. It does not automatically answer what would happen under a different action.
Model-based control demonstrates that mammalian-cell process parameters can be managed through models embedded in feedback structures [20]. Such systems provide evidence for explicit intervention interfaces.
Machine-learning models can also support model-predictive controllers that compare candidate actions [21]. Their usefulness remains conditional on training coverage, process stability, and model adequacy.
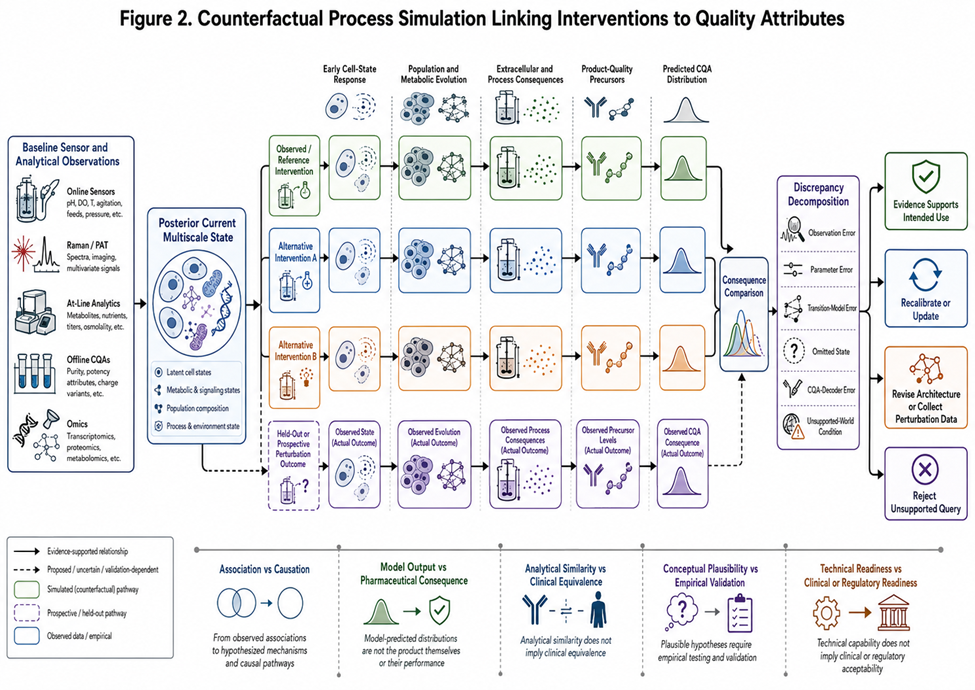
Counterfactual simulation is therefore defined here as comparing alternative intervention-conditioned trajectories from an equivalent estimated starting state. Causal interpretation requires designed perturbations or defensible identification assumptions, not predictive accuracy alone.
Prediction of critical quality attributes
A bioprocess world model must connect biological and process evolution to product quality rather than terminate at biomass or metabolite prediction. Raman spectroscopy combined with neural models can predict selected cell-culture quality attributes [22].
Automated analytical platforms can provide direct observations of monoclonal-antibody N-linked glycosylation during process development [23]. Such measurements can support both state updating and consequence evaluation.
The proposed quality decoder distinguishes intermediate quality precursors from final CQAs. It should preserve plausible mediation through metabolism, population state, extracellular conditions, and processing history.
CQA prediction remains product-, method-, and context-dependent. A predicted analytical attribute does not by itself establish release suitability, clinical performance, analytical equivalence, or regulatory acceptability.
Updating from sensor and analytical data
A static model can lose validity when instruments, raw materials, cell populations, or operating policies change. Just-in-time calibration offers one method for adapting generic Raman models to local culture conditions [24].
Online models also require continuing assessment and maintenance rather than one-time calibration [25]. This requirement becomes more important when predictions influence subsequent actions.
The proposed update pathway separates state assimilation, parameter recalibration, model retraining, and structural revision. Increasing residual error should not automatically authorize unrestricted learning.
Updates should be gated by data quality, change classification, uncertainty behavior, and revalidation requirements. Historical knowledge must be retained unless evidence justifies replacement.
Table 2 organizes the evidence, constructs, relationships, uncertainties, and boundary conditions required for testable propositions, evidence requirements, and validation criteria for the bioprocess world model for simulating cell-state evolution, manufacturing.
Table 2. Testable propositions, evidence requirements, and validation criteria for The Bioprocess World Model for Simulating Cell-State Evolution, Manufacturing.
|
Architecture layer or process stage |
Core function |
Information or material flow |
Interaction with other components |
Validation criterion |
Potential failure mode |
Human or experimental responsibility |
Readiness boundary |
|
State estimation |
Infer current latent state |
Measurements to state distribution |
Supplies transition and quality models |
Held-out observations remain compatible with estimated uncertainty |
Confident but incorrect state |
Review sensor validity and latent-state assumptions |
Component verification only |
|
Temporal transition |
Predict future evolution |
Current state and time to future state |
Couples intracellular, population, and process layers |
Prospective trajectories remain coherent over declared horizons [19] |
Error accumulation |
Design temporal holdouts |
Not counterfactual readiness |
|
Intervention interface |
Condition trajectories on actions |
Action plus current state to conditional future |
Connects controller and transition model |
Planned interventions produce distinguishable predicted and observed consequences [20] |
Policy confounding |
Conduct controlled perturbations |
Requires represented action range |
|
Population evolution |
Represent heterogeneity |
Phenotype distributions across time |
Influences process demand and quality precursors |
Phase or phenotype changes are reproduced under challenge [17] |
Bulk averaging |
Collect population-resolved evidence |
Limited by observation resolution |
|
Quality decoder |
Predict selected CQAs |
State trajectory to CQA distribution |
Receives metabolic, process, and analytical inputs |
Prospective CQA consequences agree within predeclared intended-use criteria [22] |
Surrogate breakdown |
Select direct quality assays |
Not release or clinical validation |
|
Data assimilation |
Update state using new evidence |
Sensor and analytical data to posterior state |
Feeds all predictive modules |
Updating improves or preserves calibration without instability [24] |
Drift amplification |
Approve data and change classification |
Controlled updating only |
|
Model maintenance |
Detect need for recalibration or revision |
Residuals and drift indicators to model lifecycle |
Governs retraining and replacement |
Maintenance actions restore bounded performance [25] |
Catastrophic forgetting |
Authorize and document model changes |
Revalidation required |
|
Uncertainty and boundary detection |
Identify unreliable queries |
State, action, and model uncertainty to alerts |
Constrains simulation and decision use |
Uncertainty increases under unfamiliar states or actions |
False confidence |
Define out-of-domain challenges |
Unsupported queries rejected |
|
Integrated readiness gate |
Match evidence to intended use |
Validation record to permitted use |
Governs human reliance |
Evidence supports the declared use without exceeding tested boundaries |
Readiness inflation |
Make final use decision |
Proposed, non-regulatory level |
Validation through perturbation and consequence prediction
Verification asks whether the model was implemented as intended; validation asks whether it is adequate for a defined use [26]. These questions should not be collapsed into one performance statistic.
CHO genome-scale model predictions can vary with reconstruction choices, constraints, and evaluation procedures [27]. Historical fit alone therefore provides insufficient evidence of consequence prediction.
Validation should challenge state transitions, intervention responses, uncertainty, and CQA consequences using held-out or prospective perturbations. Validity requires both correct implementation and evidence that predicted consequences survive appropriately designed challenges [26, 27].
No universal threshold is proposed. Acceptance criteria should be specified before testing and matched to the consequences of error, product context, operating range, and intended decision.
Failure modes and readiness levels
Hybrid stoichiometric and data-driven methods may improve intracellular-flux prediction while retaining sensitivity to training distributions, model structure, and missing mechanisms [28].
Additional failures include partial observability, non-identifiability, clonal drift, analytical drift, feedback-induced distribution shift, scale dependence, and omitted quality mediators.
Model-based bioprocess development requires staged evidence linked to intended use rather than complexity alone [29]. A larger model is not necessarily a more mature model.
The proposed readiness sequence is: conceptual specification; verified components; retrospective integrated coherence; prospective prediction; perturbation consequence validity; and bounded decision evaluation.
These levels are research classifications, not regulatory categories. Progression requires evidence appropriate to the next intended use and may regress when the product, cell line, scale, instrument, or intervention domain changes.
Limitations and research agenda
AI-enabled bioprocess automation still requires stronger integration, validation infrastructure, oversight, and human–machine task allocation [30]. World models amplify these needs because their errors may propagate across several linked modules.
Cell-free manufacturing provides an important boundary case: its kinetic state and material transformations differ fundamentally from living-cell population evolution [31]. Each manufacturing modality therefore requires a separately declared world.
Research priorities include intervention-rich datasets, population-resolved measurements, quality-mediated causal tests, cross-scale transport studies, uncertainty calibration, controlled updating, and comparison against simpler task-specific models.
Figure 2 presents the original conceptual synthesis for counterfactual process simulation linking interventions to quality attributes, showing how the article’s principal components, evidence relationships, uncertainties, and decision boundaries are connected.
|
|
|
Figure 2. Counterfactual Process Simulation Linking Interventions to Quality Attributes |
CONCLUSION
The proposed bioprocess world model reframes manufacturing modeling as the bounded simulation of evolving multiscale states, explicit interventions, uncertainty, and quality consequences. Its value depends on transparent world boundaries, comparison with simpler models, controlled updating, prospective perturbation testing, and intended-use-specific evidence. The architecture is a testable conceptual framework, not an empirically validated, universally applicable, regulator-endorsed, or deployment-ready manufacturing system.
ACKNOWLEDGMENTS: None
CONFLICT OF INTEREST: None
FINANCIAL SUPPORT: None
ETHICS STATEMENT: None
 IJPRAS